Over the past year, the way our team builds software has fundamentally shifted. We've moved toward an AI-first, spec-driven development approach, where developers write clear specifications and let AI models handle large portions of the implementation. The productivity gains are real. Tasks that used to take a week now take a day.
But there's a quiet risk in this new way of working that we don't think our industry is talking about enough:
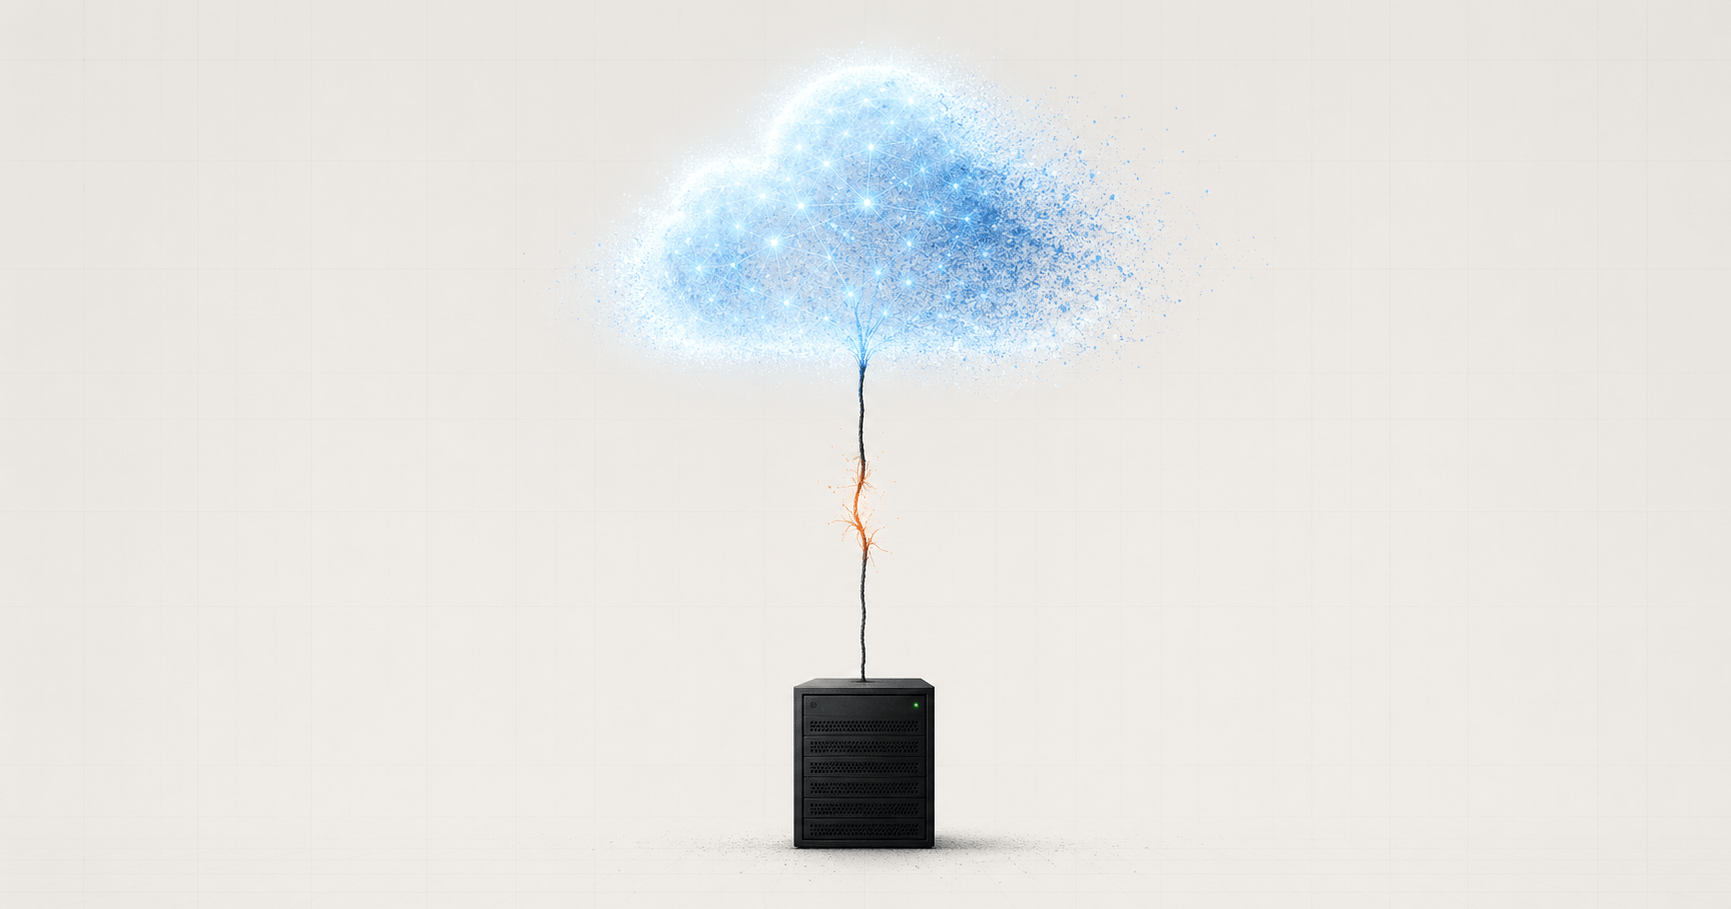
Most of us have built our entire development workflow on infrastructure we don't own.
The dependency we don't see
Claude. GPT. Gemini. The frontier models from Anthropic, OpenAI, and Google power most of the AI-assisted coding tools developers use every day, including Cursor, Copilot, Claude Code, Windsurf, and dozens more. Every spec we write, every code review the AI runs, every refactor it suggests… it all flows through APIs we rent by the token.
Now ask yourself:
- What happens if pricing doubles next quarter?
- What happens if a model your team depends on gets deprecated overnight?
- What happens if your industry introduces compliance rules that prohibit sending source code to third-party servers?
- What happens if a provider decides your account or use case no longer fits their policy?
These aren't hypothetical scenarios. Pricing has already changed. Models have already been retired. Accounts have already been shut down with little warning. The whole stack many of us depend on is, strictly speaking, borrowed.
The case for local infrastructure is getting stronger
The open-source LLM landscape has changed dramatically over the last 12 to 18 months. Models like Llama 3.x, Qwen 2.5 Coder, DeepSeek, and Mistral are now genuinely useful for real engineering work. Not at frontier model levels for the hardest reasoning tasks, but very capable for the 80% of everyday development: boilerplate, refactors, test generation, documentation, code review, and diff explanation.
What used to require a data center can now run on:
- A well-spec'd Mac Studio or Mac Mini cluster with unified memory
- A workstation with one or two consumer GPUs
- A modest on-prem server for an entire team to share
The math is starting to look interesting. If a team of ten developers is paying somewhere between $30 and $200 per developer per month on AI tooling, across IDE assistants, chat subscriptions, and API usage, that's a meaningful annual line item. A capable local inference setup can pay for itself within a year or two, and at the end of it, you still own the hardware, the weights, and full control over your code.
It's not all or nothing
We're not arguing every company should rip out their cloud AI tomorrow. Frontier models are still ahead on the hardest tasks, and probably will be for a while. But a hybrid setup is becoming very realistic:
- Local models for routine generation, autocomplete, internal documentation, code review, and anything involving sensitive or proprietary code.
- Cloud frontier models for architecture decisions, complex debugging, and the genuinely hard problems.
The strategic question isn't "local vs cloud." It's this: do we want a single point of failure sitting in the middle of our entire development pipeline, or do we want to own at least part of our AI capability?
Some open questions for the community
We'd genuinely like to hear from others working through this:
- Has your team experimented with local LLMs for actual development work? What's working in real production use, not just in benchmarks?
- How much is your organization spending per developer per month on AI tooling right now? We're curious where the real numbers sit, because the public conversation feels disconnected from what teams are actually paying.
- Are CTOs and CFOs starting to treat AI inference as a line item worth bringing in house, the way some companies moved predictable workloads back from cloud to on-prem?
- What hardware setup would you recommend for a small or mid-sized engineering team that wants to run capable local models without overbuilding?
If you've gone down the local LLM path, whether it worked beautifully or fell apart, we'd really like to hear your story. The collective experience here is more valuable than any vendor's marketing deck.